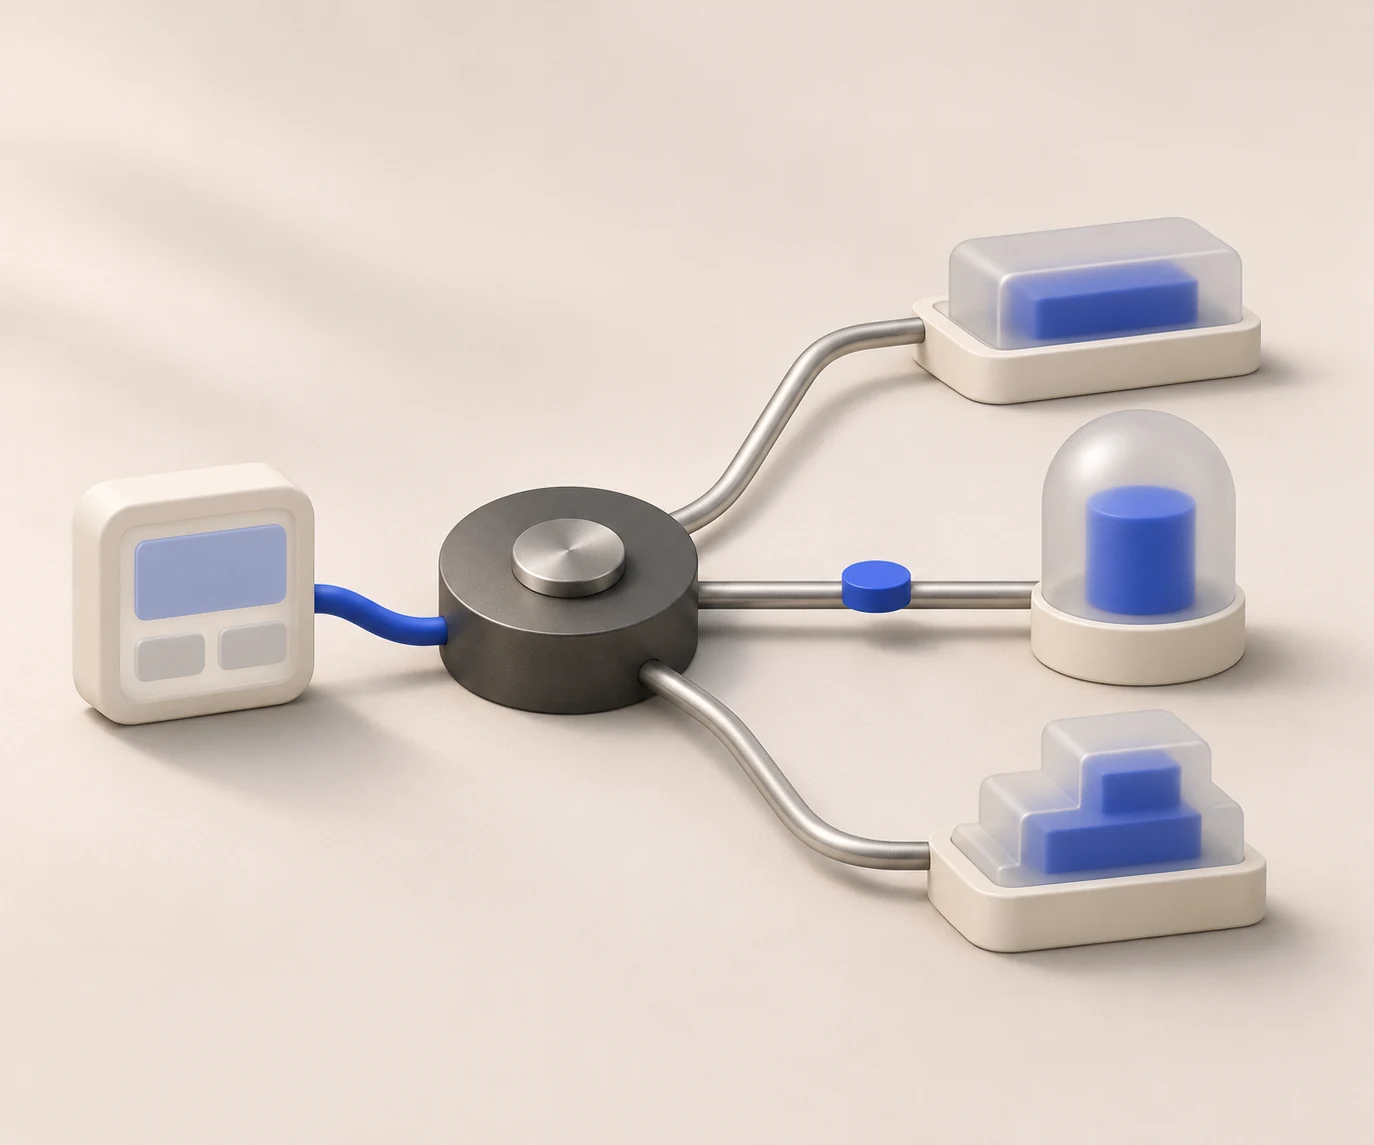
Running multiple agent backends means your application can send a task to more than one model, provider or agent harness through a single integration, and choose the backend per task instead of hard-coding one. The practical answer is to put one interface between your product and the backends, so routing, failover, cost tracking and sandboxing live in one layer rather than in every feature. HarnessRouter is built for exactly that layer: one API in front of supported agent harnesses, with models, tools and sandboxes as interchangeable parts.
TL;DR
- A "backend" for an agent product is more than a model: it is the harness, the model, the provider and the sandbox that run a task. Each can be configured independently where the interfaces and capabilities are compatible.
- Add backends because tasks differ in quality, latency and cost needs, and because a single provider is a single point of failure. Do not add them to look sophisticated: research on model pools shows that arbitrary additions can lower quality.
- Fail over only when a request can be repeated safely. Partial output and uncertain tool actions should not be blindly replayed.
- Measure backends at the workflow level: latency percentiles, error rates, refusal rates, fallback frequency and task acceptance.
- Keep routing, sessions, files and sandboxes behind one API so that adding or removing a compatible, supported backend is a configuration change.
What multiple agent backends actually are
Two ideas are often confused. A multi-agent system coordinates several agents with different roles toward one goal: a planner, a coder, a reviewer. Multiple backends is an infrastructure question: for a given agent task, which execution stack handles it, and can that choice change without rewriting the application?
In an agent product, a backend usually has four parts:
| Part | What it decides | Example variation |
|---|---|---|
| Harness | The loop that plans, calls tools and manages context | A coding harness versus a general-purpose one |
| Model | The reasoning engine behind the loop | A flagship model versus a small, fast one |
| Provider | Who serves the model and where | Different vendors or regions |
| Sandbox | The isolated environment where the agent runs code and touches files | Different runtimes and isolation levels |
A plain LLM router chooses among models. An agent backend layer can configure all four, because the same model behaves differently inside different harnesses. If you want the model-level version first, our guide to what an LLM router is covers it, and the backend for AI agents describes what the complete stack includes.
Why teams run more than one backend
Three pressures push teams there.
Tasks differ. Summarizing a ticket and refactoring a repository do not need the same engine. Sending everything to the strongest model can overpay on easy tasks; sending everything to a cheap model can fail on hard ones. Per-task selection is the lever. Our AI model selection method walks through matching models to tasks, and LLM cost optimization shows where the savings come from.
Providers fail and change. An outage, a rate limit, a price change or a silent model update at one provider can halt a feature that depends on it. A tested, independent second route can reduce disruption when it has the required capacity, capabilities and time to finish.
Data location matters. Some customers require that data be processed in specific regions or on infrastructure you control. Teams in that position sometimes include a self-hosted model as one backend, which is where guides on local AI hardware for running LLMs become relevant to the routing decision.
Note what this list does not say: more backends is not automatically better. A 2026 arXiv study of model-selection strategies found that, on challenging scientific benchmarks in the tested multi-agent setups, expanding the candidate pool often degraded performance below the best single model, and that selecting within one model family gave the best relative results. The lesson is to add a backend for a named reason, such as a cost tier, a region or a fallback, and to remove it when the reason disappears.
Routing: choosing the backend per task
A routing policy answers one question per request: given this task, which backend should run it, optimized for what? The usual objectives are quality, latency and cost, and they conflict. A workable policy has three layers.
- Hard constraints. Region, data-handling rules, required tool support and context length remove backends before any scoring happens.
- Task class. Map task types to a default backend: classification and extraction to a small model, multi-step code changes to a capable harness with a strong model.
- Objective. Among the eligible backends, pick the one that wins on the objective you set for that task: lowest cost within a quality floor, or lowest latency for interactive flows.
The quality floor needs evidence from your own tasks. Public rankings rarely match your prompts, so keep a small evaluation set per task class and rerun it whenever you change a backend, a prompt or a model version. HarnessRouter includes benchmarking tools for this purpose, and lets teams use benchmark results to configure compatible harness, model and module choices for quality, latency or cost.
A caution on single-model assumptions: tiers do not always behave as price suggests. Teams regularly find a smaller model matching a larger one on a narrow task, which is the reason to measure per task class instead of assuming the expensive option is the safe one.
Failover without making things worse
Failover is retrying a request through another approved backend when the primary cannot serve it. OpenAI's engineering guidance on provider failover is explicit about the conditions: it helps only when the request can be repeated safely and the alternative meets the workflow's quality, feature and latency requirements. It also warns that partial output or uncertain tool actions should not be blindly replayed.
For agents this matters more than for single completions, because an agent run has side effects. A run that already wrote a file, opened a pull request or called an external API cannot simply be restarted elsewhere. A safe design separates three cases:
- Failure before any action. For a retryable failure, retry on an approved, compatible and healthy backend within shared retry, time and spend budgets.
- Failure mid-run with idempotent steps. Resume only from a portable checkpoint supported by the alternative runtime, with compatible tools and artifacts, enforced idempotency and reconciliation of prior actions.
- Failure after uncertain side effects. Stop, surface the state and let a human or a reconciliation step decide.
This is why session management belongs in the shared layer rather than inside any one harness. Keeping session history, files and environment access behind one API simplifies continuity. Moving an in-progress run still requires a portable checkpoint, compatible runtime state and tools, and reconciliation of prior actions. Our overview of infrastructure for AI agents lists the layers involved.
How to compare backends
A leaderboard score is not a comparison. A 2026 comparative analysis of LLM providers argues that reliability should be judged at the workflow level: translate provider commitments into business terms such as acceptable downtime, maximum latency, recovery time and data-loss tolerance, then track what production actually does. The metrics it points to are:
| Metric | What it reveals |
|---|---|
| Latency percentiles (p50, p95, p99) | Tail behavior that averages hide |
| Error rate | Hard failures per backend |
| Refusal rate | A backend that is up but declining valid work |
| Fallback frequency | How often the primary is not carrying its load |
| Task acceptance rate | Whether outputs pass your own downstream check |
The last two catch what the analysis calls gray failures: a provider that is available but quietly degrading. Uptime dashboards will not show them; acceptance and fallback rates will.
Cost belongs in the same table, expressed per accepted task, not per token. A cheap backend with a low acceptance rate and frequent retries can cost more than a pricier one that succeeds the first time. Our breakdown of LLM inference costs separates the line items that make up that number.
Operating multiple backends in production
The routing layer becomes critical-path infrastructure, so treat it as such.
Log the full chain. For each run record the backend chosen, model version, permitted prompt metadata, parameters, tokens, latency, cost and outcome, with redaction and retention controls for sensitive data. The same provider analysis notes that even hosted models configured for deterministic output can vary between calls, which is the reason to log versions and pin them where supported, and to canary-test changes in regulated workflows.
Alert on fallback rate. A router that silently falls back hides a degraded experience. A rising fallback rate can be an early signal that a primary backend is struggling.
Rehearse the degradation plan. The analysis recommends a runbook that states when to switch models, queue requests, disable noncritical AI features or escalate to people, and it stresses that fallback designs that were never rehearsed tend to fail when needed. Run the drill before the incident.
Isolate execution. If an agent can trigger tools, whatever those tools can do is the blast radius of a bad prompt or a manipulated retrieval result. Running each task in an isolated sandbox limits local file and process effects. External tool actions still need separate authorization, network controls and scoped credentials, regardless of which backend produced the action.
Control keys and spend. Per-team budgets and rate limits keep one runaway agent from consuming the month's allowance. With bring-your-own-key setups, your provider keys stay yours; HarnessRouter lists a BYOK routing fee of 0% for up to $25,000 in monthly model usage at list prices, with a 5% routing fee above that volume. Model charges go through your provider account; agent work and memory remain separately billable.
Adding backends to an existing product
A staged rollout keeps risk low.
- Inventory what you call today. List each agent or model call, its task class, its current cost and its failure history.
- Put one interface in front. Route existing traffic through a single API without changing behavior. Compare latency in staging, then release to a small share of production traffic.
- Add observability before adding backends. Tracing, cost per feature and acceptance rate need a baseline before you can tell whether a new backend helps.
- Introduce one backend for one reason. A cheaper tier for a high-volume task, or a second provider as failover for your most critical flow. Run your evaluation set, then canary.
- Pin versions and rehearse. Pin model versions where supported, set alerts on fallback rate and run the degradation drill.
- Review quarterly. Remove backends that no longer earn their place.
When is a single backend enough? When one model meets your quality floor on every task, costs are acceptable, and an outage of that provider is tolerable. Many early products are in that position. The moment any of those conditions breaks, the interface from step 2 is what lets you change without a rewrite, so it is worth adopting before you need a second backend. If you are also weighing a thinner layer, what an LLM proxy does and where it stops and how a unified LLM API differs are the relevant comparisons.
Where HarnessRouter fits
HarnessRouter is an open-source unified interface and cloud platform for integrating, benchmarking and managing multiple agent harnesses, such as Codex, Claude Code, Hermes, DeepSeek and Pi, in production applications through one API. It covers agent session management, file handling, plugins, environment provisioning and a serverless agent runtime lifecycle, and it is built on the open Unified Harness Protocol (UHP), so no single harness or provider locks you in. For how UHP relates to tool protocols, see UHP vs MCP.
Plans start at $0 per month (Free), then Developer at $20 per month, Production at $200 per month and Scale at $1,000 per month, with an Enterprise plan on request; tracing is in beta and included with Scale, with current add-on terms on the pricing page. The top-up credit processing fee is 5.5%, with a $0.80 minimum. Details are on the pricing page. Teams that prefer to self-host can use the Community Edition.
For product features that call an agent over HTTP, the AI agent API guide shows the integration shape.
Our perspective
The harness is the layer teams underestimate. Most routing discussions stop at models, yet the loop that plans, calls tools and manages context changes outcomes as much as the model does. That is why we treat harnesses, models, providers, skills, tools, plugins, memory and sandboxes as interchangeable building blocks behind one interface.
We think this layer should be open and commoditized. That is the reason we initiated the Unified Harness Protocol: if the harness layer follows an open standard, you can adopt the best harness for each task today and replace it tomorrow without rebuilding your product around it.
The goal is that a task gets the right combination for quality, latency or cost, runs in an isolated sandbox, and leaves a trace you can evaluate. Our formula is designed to cut agent costs by over 90% by sending each task to the combination it actually needs, and we built benchmarking in so that your own evaluation set, not ours, decides the routing. Validate the claimed savings on your own workload.
FAQ
Is using multiple agent backends the same as a multi-agent system?
No. A multi-agent system divides one goal among several cooperating agents. Multiple backends means that any given agent task can be executed by different harness, model, provider or sandbox combinations. You can use backend routing with a single agent, and a multi-agent system can run all its agents on one backend.
How many backends should I start with?
Start with one primary and add a second only for a stated reason, such as failover for a critical flow or a cheaper tier for a high-volume task. Research on model pools shows that growing the candidate set can reduce quality, so each addition should pass your own evaluation set.
Can I switch backends in the middle of an agent run?
Only when it is safe. OpenAI's failover guidance says partial output and uncertain tool actions should not be blindly replayed. Before any action, retry only eligible failures on approved, compatible and healthy routes within shared budgets. After side effects, reconcile outcomes and resume only from a portable checkpoint with compatible runtime state, tools and enforced idempotency.
Do I have to give up my own provider keys?
No. HarnessRouter supports bring-your-own API keys for model transactions, and its published BYOK routing fee is 0% for up to $25,000 in monthly model usage at list prices, with a 5% routing fee above that volume. Agent work and memory remain separately billable. Pricing for each plan is on the pricing page.